TL;DR
Put a query-agnostic task description before the document and the question after it: the document stays prefix-cacheable, and LongBench accuracy is the best of the five layouts tested.
Abstract
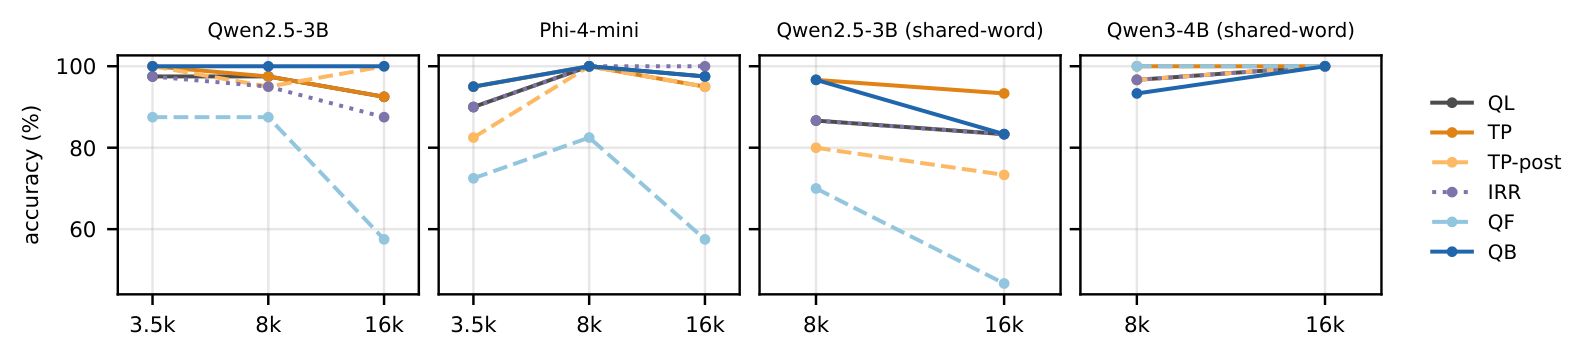
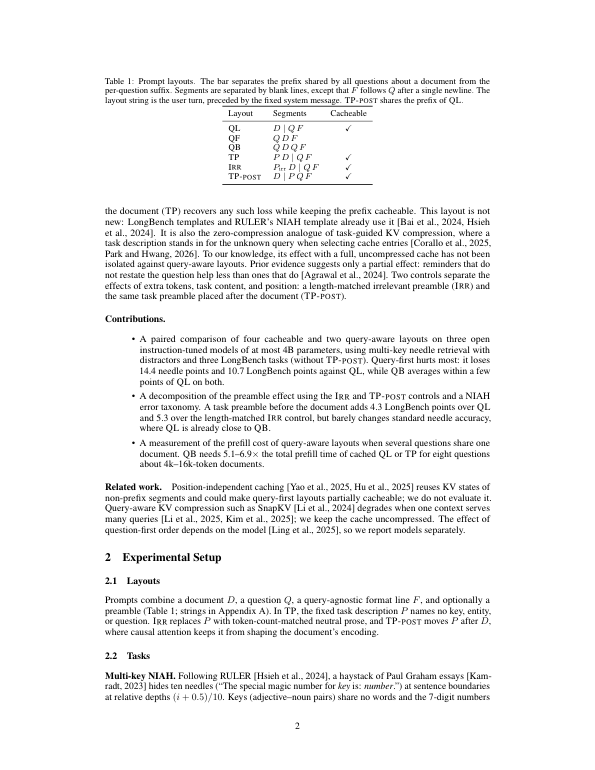
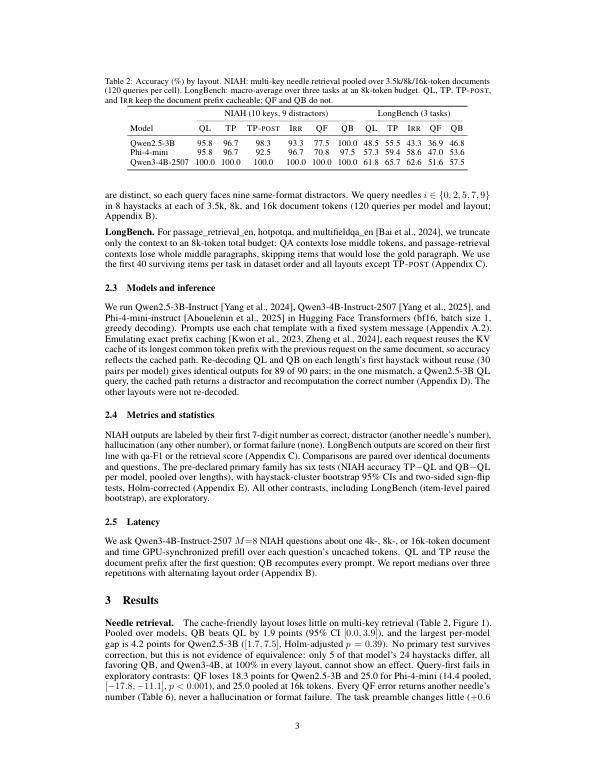
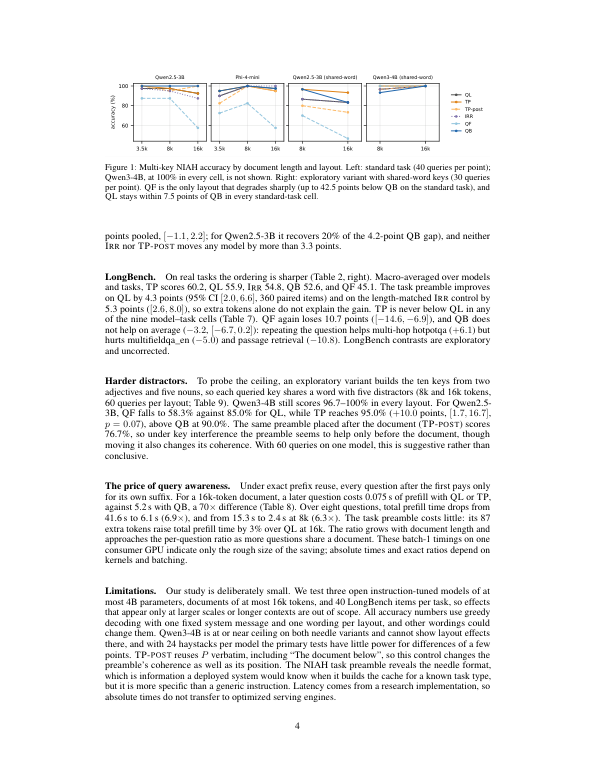
Exact prefix caching reuses the key-value cache of a shared document only when each question comes after it, yet practitioner guides disagree on whether questions should precede long documents. We measure what this cache-friendly, query-last layout costs. On three open instruction-tuned models with 3-4B parameters, we compare six prompt layouts on multi-key needle retrieval with distractors at 3.5k-16k tokens and five of them on three LongBench tasks, and we time prefill when eight questions share one document. Query-first prompts are the clear failure: they cost the two models that are not at ceiling 18.3 and 25.0 points of needle accuracy, always by returning a distractor's value, and lose 10.7 LongBench points relative to query-last. Repeating the question on both sides of the document gains at most 4.2 needle points for any model, which is not significant after correction, scores 3.2 points lower on LongBench, and needs 6.9x the prefill time for eight questions about a 16k-token document. A query-agnostic task description placed before the document, which keeps the document cacheable, barely changes needle accuracy and raises LongBench scores by 4.3 points over query-last, while a length-matched irrelevant preamble does not. In our setting, describing the task before the document and asking the question after it gives the best LongBench average of the five layouts we test, at nearly the prefill cost of query-last.
Results
Paper
Download PDF (13 pages)
BibTeX
@inproceedings{ma2026describe,
  title  = {Describe the Task First, Ask Last? Query Placement and Prefix-Cache Reuse in Small Long-Context Models},
  author = {Qinzhen Ma and Jialin Wu and Shichen Tang},
  booktitle = {NeurIPS 2026 Workshop on Long Context Foundation Models},
  year   = {2026}
}